Execute LLM EndpointAdmin Scope
LLM Serving
QuickML now provides Generative AI services by hosting Large Language Models and Vision Language Models (VLM) under Generative AI section in the console. LLM Serving is equipped with Chat instance with a set of parameters for each model to provide additional control over its responses.
LLM serving is equipped with two interaction modes with language models. The only difference between these two is keeping the context of prior messages while responding to the query. Let’s take a quick look at the explanation.
- Single-shot mode: Each prompt request to the model is treated independently while generating the response, with no memory of previous turns.
- Conversation mode: Maintains context throughout the session. Prior turns are passed as context, allowing multi-turn conversations.
Execute LLM Endpoint
With Catalyst QuickML, you can tune the responses of available large language models according to your needs and access them from your application using authenticated endpoints. An LLM Endpoint is created from a saved parameter configuration, so the model used, tools, Instructions, system prompt, and generation parameters you tested in the console are exactly what your application calls.
-
You will need to have the LLM endpoint created and published in your project using the Catalyst console, before you execute the code snippets below.
-
The model and its parameters are fixed at the time of endpoint creation and cannot be overridden through the SDK.
-
QuickML is currently available to Catalyst users accessing from the US, IN, & EU data centers.
The SDK method you call depends on the interaction mode the endpoint was configured with:
| Interaction mode | SDK method |
|---|---|
| Conversation mode OFF (Single shot mode) | askLlm(endpointKey, prompt) |
| Conversation mode ON | converseWithLlm(endpointKey, prompt, conversationId) |
a. Generate an LLM response
Single-shot interaction with a language model requires a prompt and a valid endpoint key. The endpoint key is generated when the LLM endpoint is created.
The askLlm(llmEndpointKey, llmPrompt) method sends a prompt to the published LLM endpoint and returns the generated response. Each request is processed independently, and no conversation context is retained between requests.
Parameter Used
| Parameter | Description | Values |
|---|---|---|
| llmEndpointKey | The unique ID of the LLM endpoint published in your project | String |
| llmPrompt | The message sent to the model | String |
Sample Code Snippet
 // -------------------------------------------------------------
// LLM - Generate Response
// ------------------------------------------------------------
    const llmEndpointKey = "";
    const llmPrompt = "";
    const llmResponse = await quickML.askLlm(llmEndpointKey,llmPrompt);
    console.log(llmResponse);
The syntax of the model response received is shown below:
{
    "status": "success",
    "result": [
        {
            "content": "The generated response text from the model.",
            "finish_reason": "stop",
            "usage": {
                "input_tokens": 42,
                "output_tokens": 128,
                "total_tokens": 170
            }
        }
    ]
}
Use this method for single-shot interaction tasks such as summarization, classification, content generation, or extraction.
b. Converse with an LLM
Conversation mode requires a prompt, a valid endpoint key, and a conversation ID. The endpoint key is generated when the LLM endpoint is created.
The converseWithLlm(llmConversationEndpointKey, llmConversationPrompt, conversationId) method sends a prompt to a published LLM endpoint while retaining the context of previous interactions in the same conversation.
Parameters used
| Parameter | Description | Values |
|---|---|---|
| llmConversationEndpointKey | Mandatory parameter. The unique ID of the LLM endpoint published in your project | String |
| llmConversationPrompt | Mandatory parameter. The message sent to the model | String |
| conversationId | Optional parameter. Identifies the conversation thread the message belongs to. | String |
Sample Code Snippet
// ------------------------------------------------------------------
// LLM - Chat with History
// ------------------------------------------------------------------
// Replace with your endpoint key copied from the Catalyst console.
const llmConversationEndpointKey = “<ENDPOINT_KEY>”;
const llmConversationPrompt = “<YOUR_PROMPT>”;
/*
- For the first request, use “-1”.
- For subsequent requests, use the conversation ID returned in the previous response.
*/
const conversationId = “<CONVERSATION_ID>”;
const conversationResponse = await quickML.converseWithLlm(llmConversationEndpointKey, llmConversationPrompt, conversationId);
console.log(conversationResponse);
The syntax of the model response received is shown below:
{
    "status": "success",
    "result": [
        {
            "conversation_id": "55663000000288001",
            "content": "The generated response text from the model.",
            "finish_reason": "stop",
            "usage": {
                "input_tokens": 310,
                "output_tokens": 96,
                "total_tokens": 406
            }
        }
    ]
}
Use this method to build chat experiences where the model must retain the context of previous interactions.
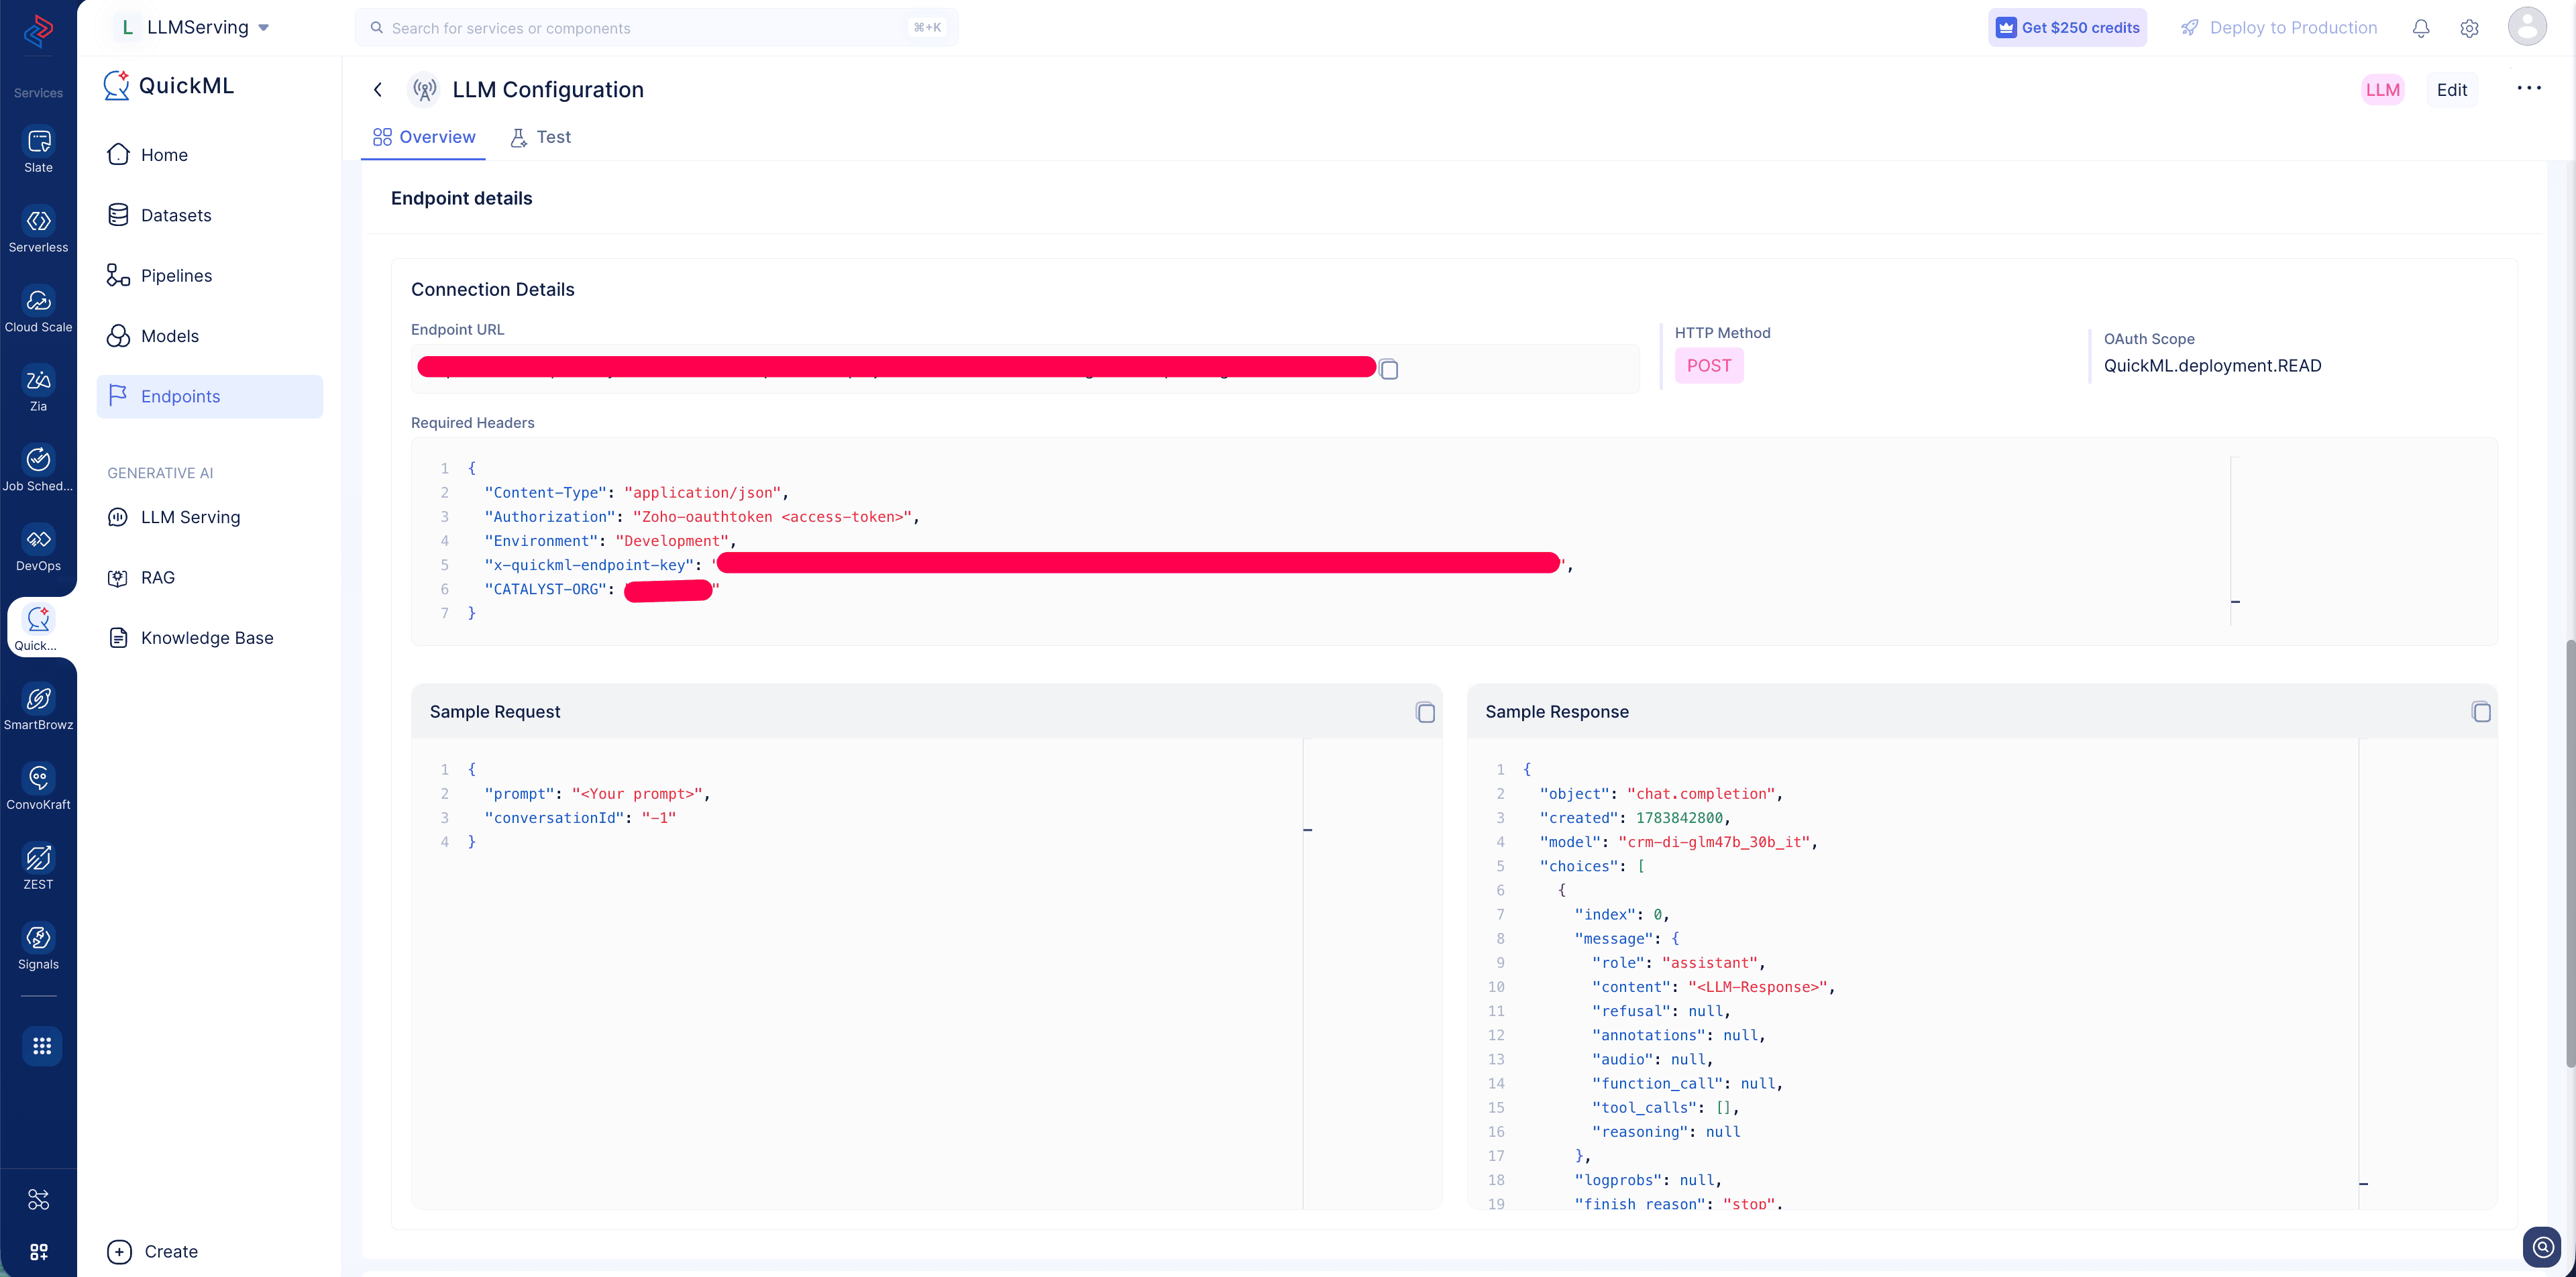
Where to find the endpoint information
Create an endpoint for your saved LLM configuration and access the endpoint details page in the Catalyst console. The page provides the Endpoint URL, required headers, and a sample request and response.
Last Updated 2026-09-15 11:25:13 +0530 IST
Yes
No
Send your feedback to us
 Ask ChatGPT
 Ask Claude
 Ask Perplexity