---
title: "Execute Vision Model Endpoint"
url: https://docs.catalyst.zoho.com/en/sdk/java/v1/quickml/execute-vision-model-endpoint/
description: "This page describes the method to execute QuickML endpoints in your Java application with a sample code snippet."
last_updated: 2026-09-23T13:11:30Z
service: QuickML
type: general
related_links:
- name: "QuickML"
url: /en/quickml/
---
#### Vision Language Model
QuickML hosts Vision Language Models in the LLM Serving module under the Generative AI section in the console. VLMs are multimodal models that accept a file object along with a text prompt and return a natural language response. The model interprets the image according to the text prompt instruction and generates an appropriate response.
Interaction with Vision Language Model works similar to single shot interaction mode with LLM. Each request must carry its own file and prompt and is processed independently, with no memory of previous requests. To analyze the same image again with a different instruction, send a new request.
**Execute Vision Model Endpoint**
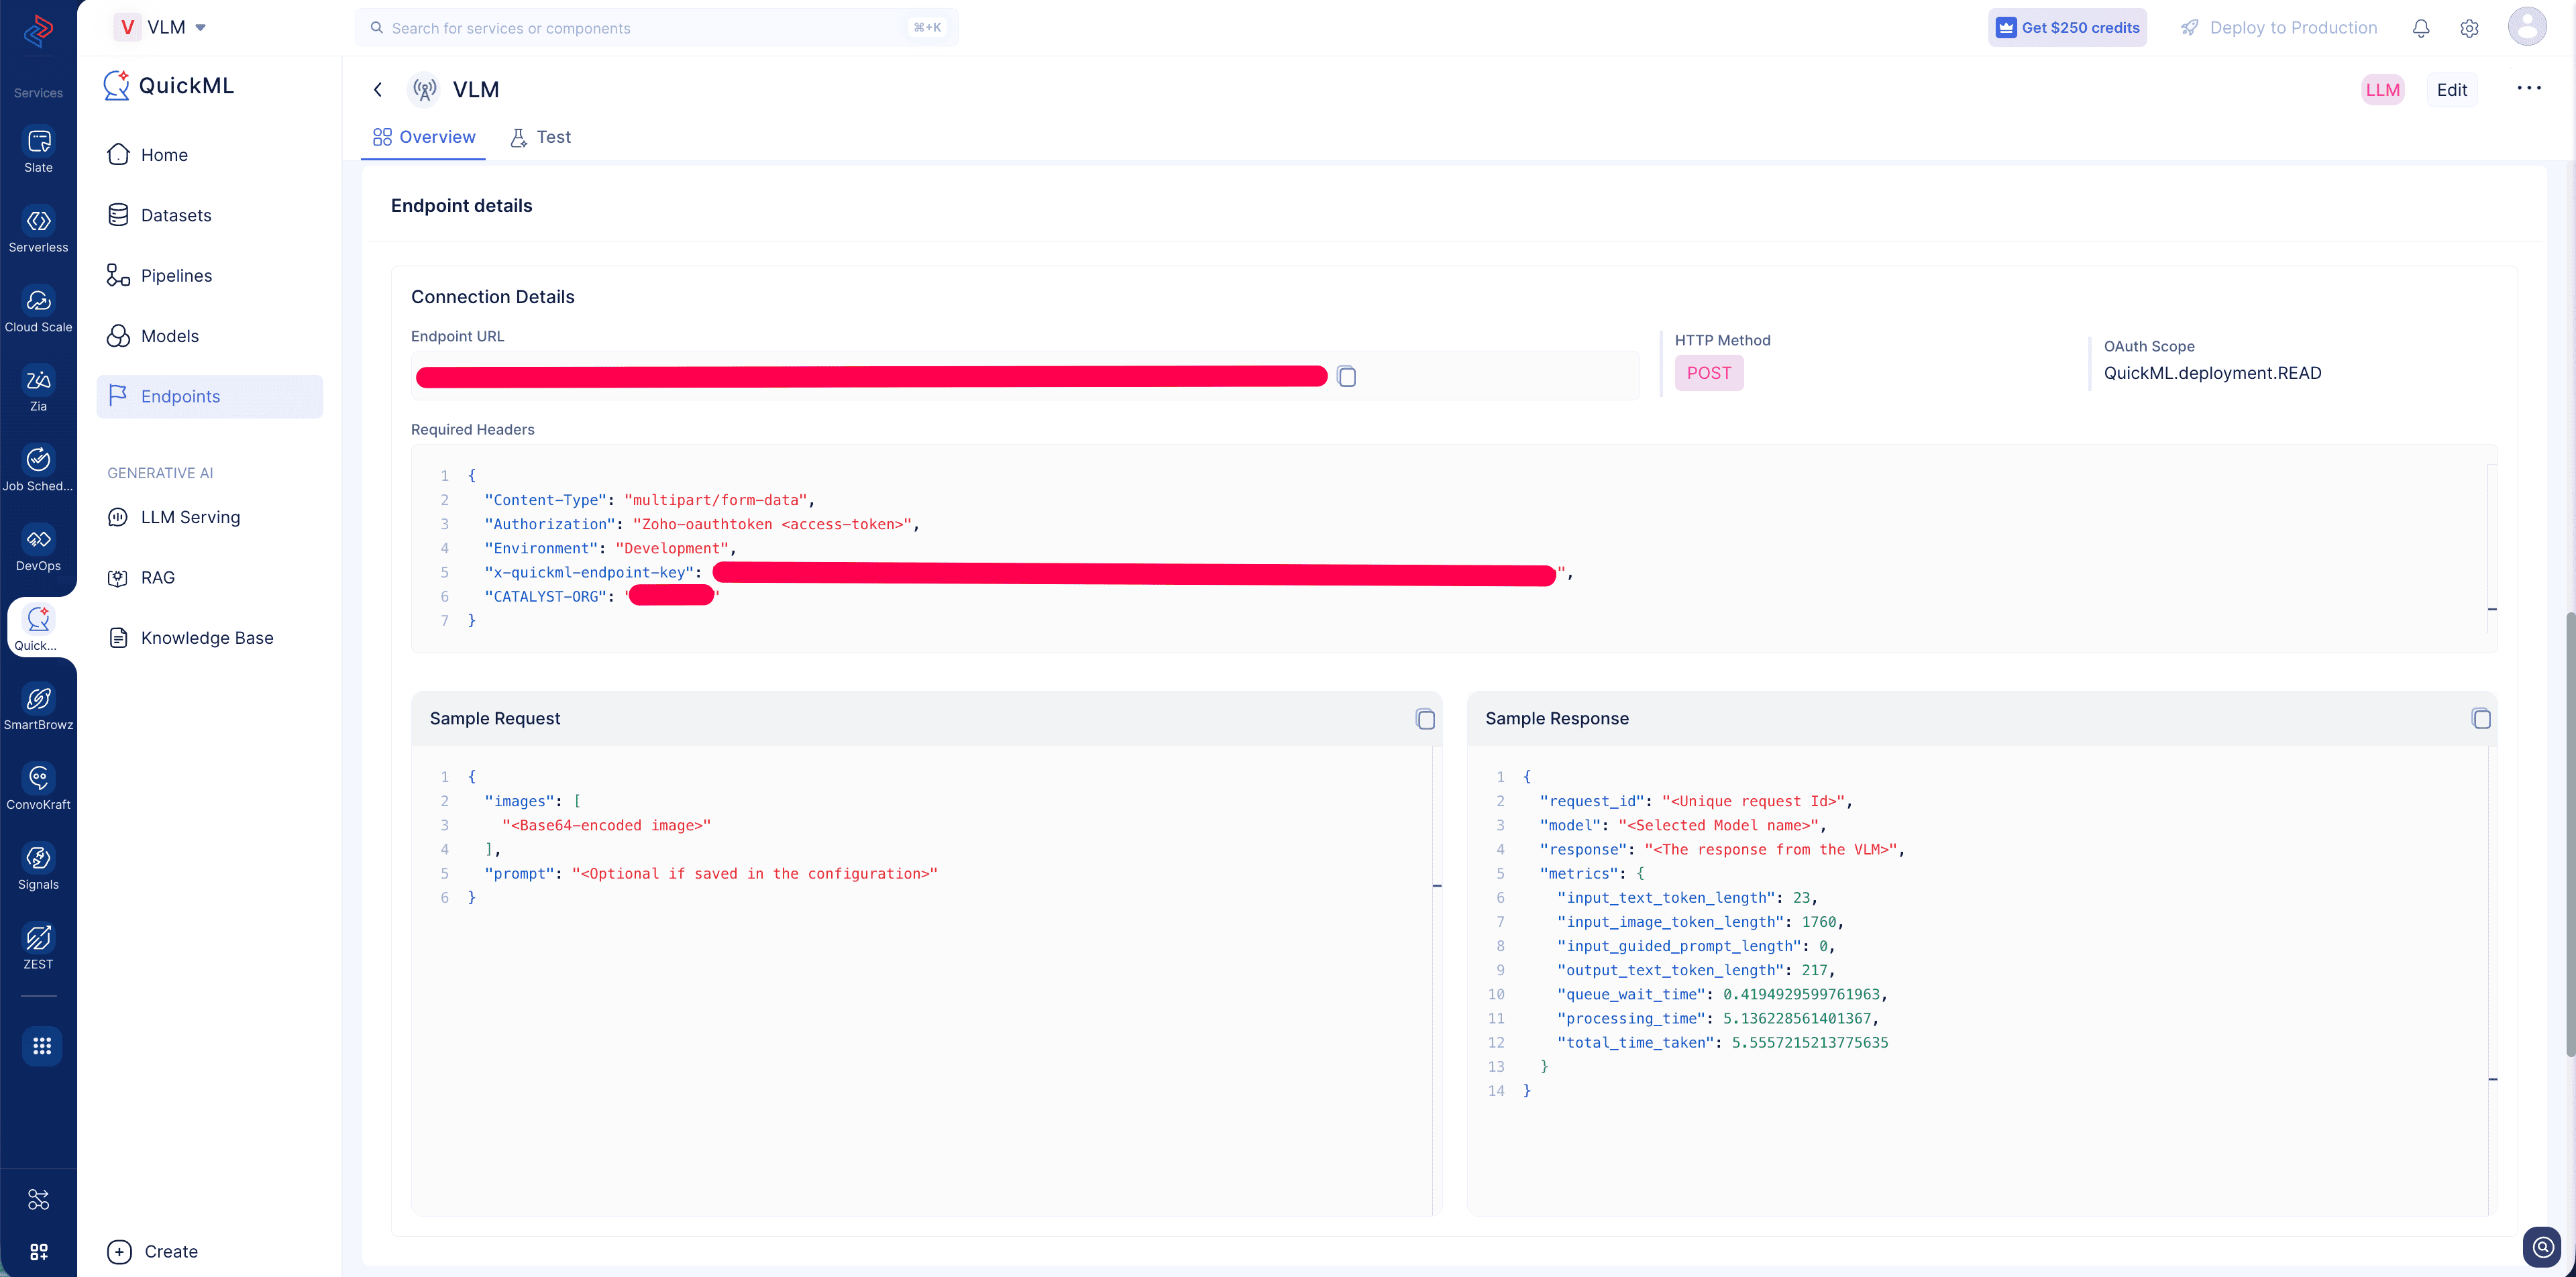
VLM is served with its own set of parameters, giving you control over the response before publishing it. You can test a model with sample images and prompts in the test interface, save the configuration, and create an endpoint from it to integrate with your application.
A Vision Model endpoint is created from a saved parameter configuration, so the model, system prompt, instructions, and generation parameters you tested in the console are exactly what your application calls. The endpoint must be created from a configuration that uses a Vision Language Model, text-only LLM endpoints do not accept image input. Open the image in binary read mode and pass the file object to the method
> **Note:**
1. You will need to have the Vision Language Model endpoint created and published in your project using the Catalyst console, before you execute the code snippet below.
2. QuickML is currently available to Catalyst users accessing from the US, IN, and EU data centers.
### a. Analyze an Image
The `analyzeImage(endpointKey, image, prompt)` method requires the endpoint key, image file, and prompt. The endpoint key is generated when the endpoint is created. This method sends an image along with an accompanying prompt to a published Vision Language Model endpoint and returns the model's response.
**Parameters Used**
Parameter Name
Definition
Value
endpointKey
The unique ID of the VLM endpoint published in your project.
String
image
The image file object to be analyzed.
File object
prompt
The task the model must perform on the image.
String
**Allowed file formats:** `.jpg`, `.jpeg`, `.png`
**File size limit:** 500 KB
**_Sample Code Snippet_**
```java
// Replace with the endpoint key copied from the Catalyst console.
String endpointKey = "";
// Replace with the path to the image you want to analyze.
File image = new File("");
// Enter the prompt describing the task to perform on the image.
String prompt = "";
ZCQuickMLDetail result = quickMlInstance.analyzeImage(endpointKey, image, prompt);
System.out.println(result.getResponse());
```
The syntax of the response received is shown below:
```json
{
"status": "success",
"result": [
{
"content": "A description of the image, as instructed by the prompt.",
"finish_reason": "stop",
"usage": {
"input_tokens": 1064,
"output_tokens": 74,
"total_tokens": 1138
}
}
]
}
```
Use Vision Language Models for tasks such as image description, document and receipt understanding, chart interpretation, and visual question answering.
**Where to Find the Endpoint Information?**
Use Vision Language Model for tasks such as image description, document and receipt understanding, chart interpretation, and visual question answering, etc.